Agentic Context Learning or ACE is a learning paradigm that lets an AI agent improve across tasks by editing the context it reads, while leaving model weights unchanged. The paper outlining the techniques show why full rewrites fail, how the playbook update works, and where the measured gains hold up.
This article explores how ACE manages these incremental adjustments to maintain long-term performance and reliability paving the way for future training Agentic LLMs.
Table of contents
What is Agentic Context Engineering?
Suppose an agent calls an API, gets an error, fixes its request, and completes a task. A week later, it faces the same API quirk. Will it repeat the error? Agentic Context Engineering, or ACE, stores the reusable lesson in a playbook that the agent reads on the next task.
Why a context needs careful updates
Many memory systems ask an LLM to rewrite everything it has learned.
For instance, memory mechanisms in GPT-6 Astra or similar agentic ecosystems require careful context management to maintain continuity across interactions without degrading accuracy.
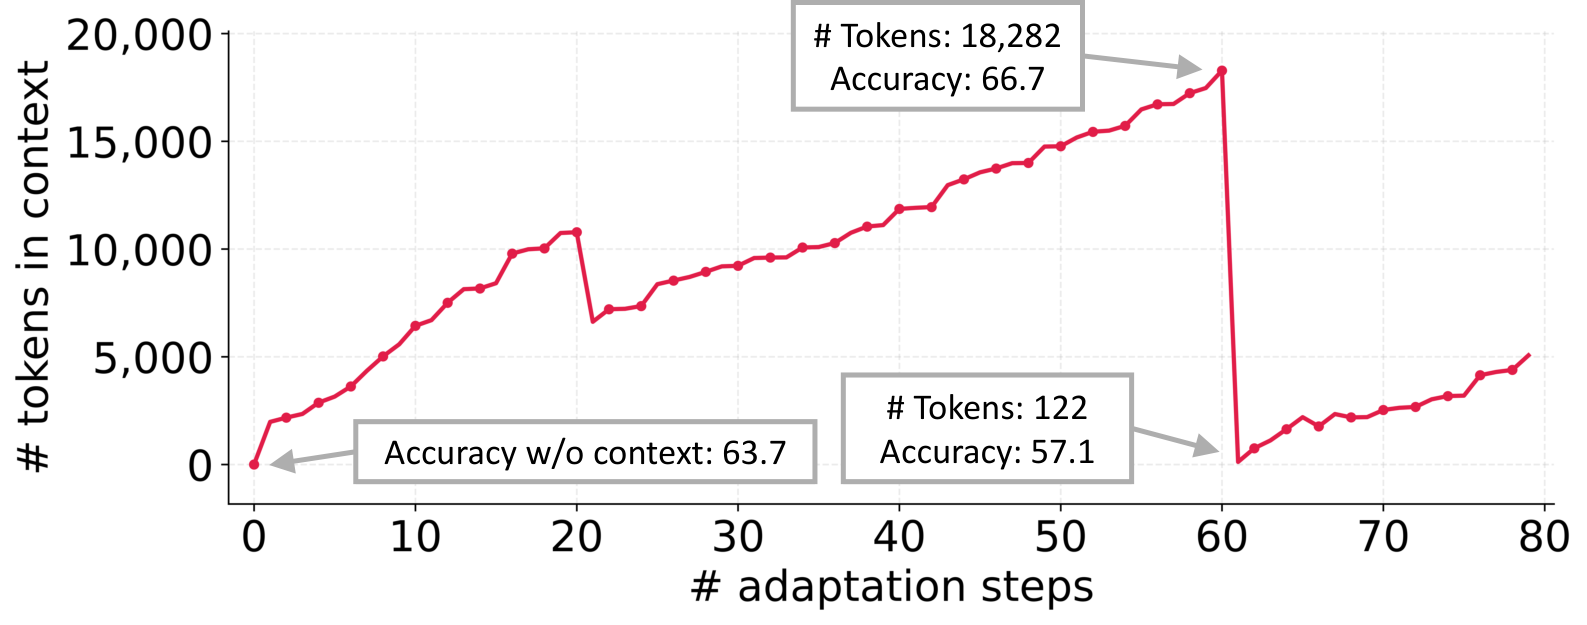
That can erase useful details. In one AppWorld case study, a Dynamic Cheatsheet context collapsed from 18,282 tokens to 122 in one step, while the reported accuracy fell from 66.7% to 57.1%. The figure shows one failure case, not a typical failure rate.
ACE avoids full rewrites.
It keeps context as small, named entries and edits the relevant entry after a task. This matters when agents repeatedly use tools or need domain rules that a generic prompt would forget.
Three part ACE loop
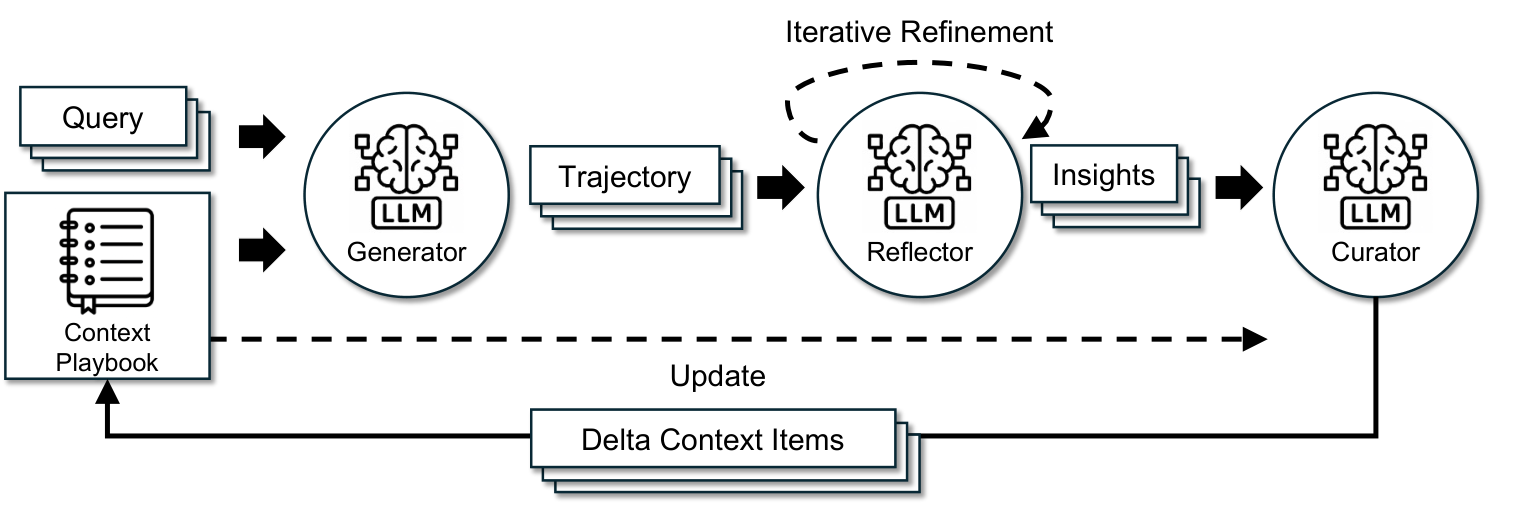
- The Generator attempts the task using the current playbook.
- The Reflector reads the attempt and feedback, then extracts a lesson.
- The Curator turns the lesson into a small delta update.
What does it store?
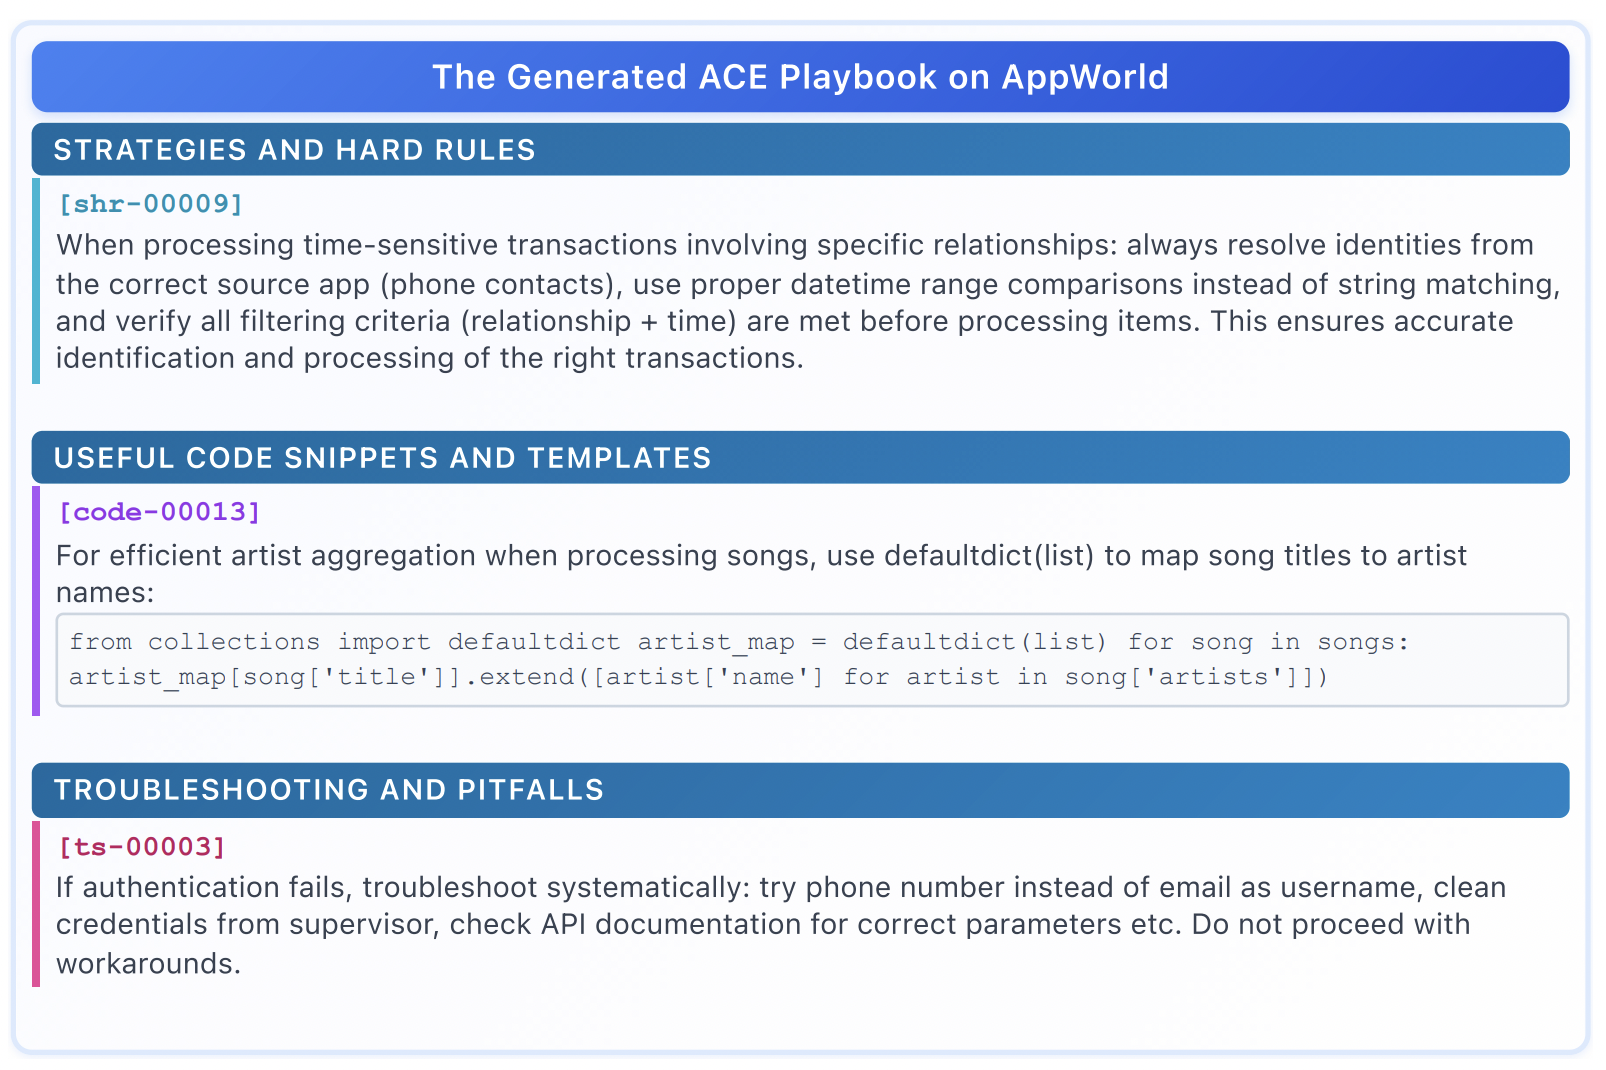
Tool-use rules, reusable code, and troubleshooting advice are some of the commonly stored data points. Entries carry IDs and helpful or harmful counters. New entries can be added; old ones can be revised, merged when they repeat each other, or pruned when the context grows.
For a simple example, imagine an agent that reads only the first page of invoice results. The next response reveals a next_page field. A useful playbook entry would say to follow that field until it is empty before totaling invoices. This is an explanatory example, not a paper run. It also shows why feedback quality matters: the system must notice the missing invoices before it can learn the right rule.
Benchmarks for ACE
The ACE paper evaluates offline adaptation, where the playbook is built before testing, and online adaptation, where the agent predicts on an item before updating its playbook from that item.
Since most LLMs that exhibit such model characteristics are at their infancy, the benchmarks would be useful to gauge its potency.
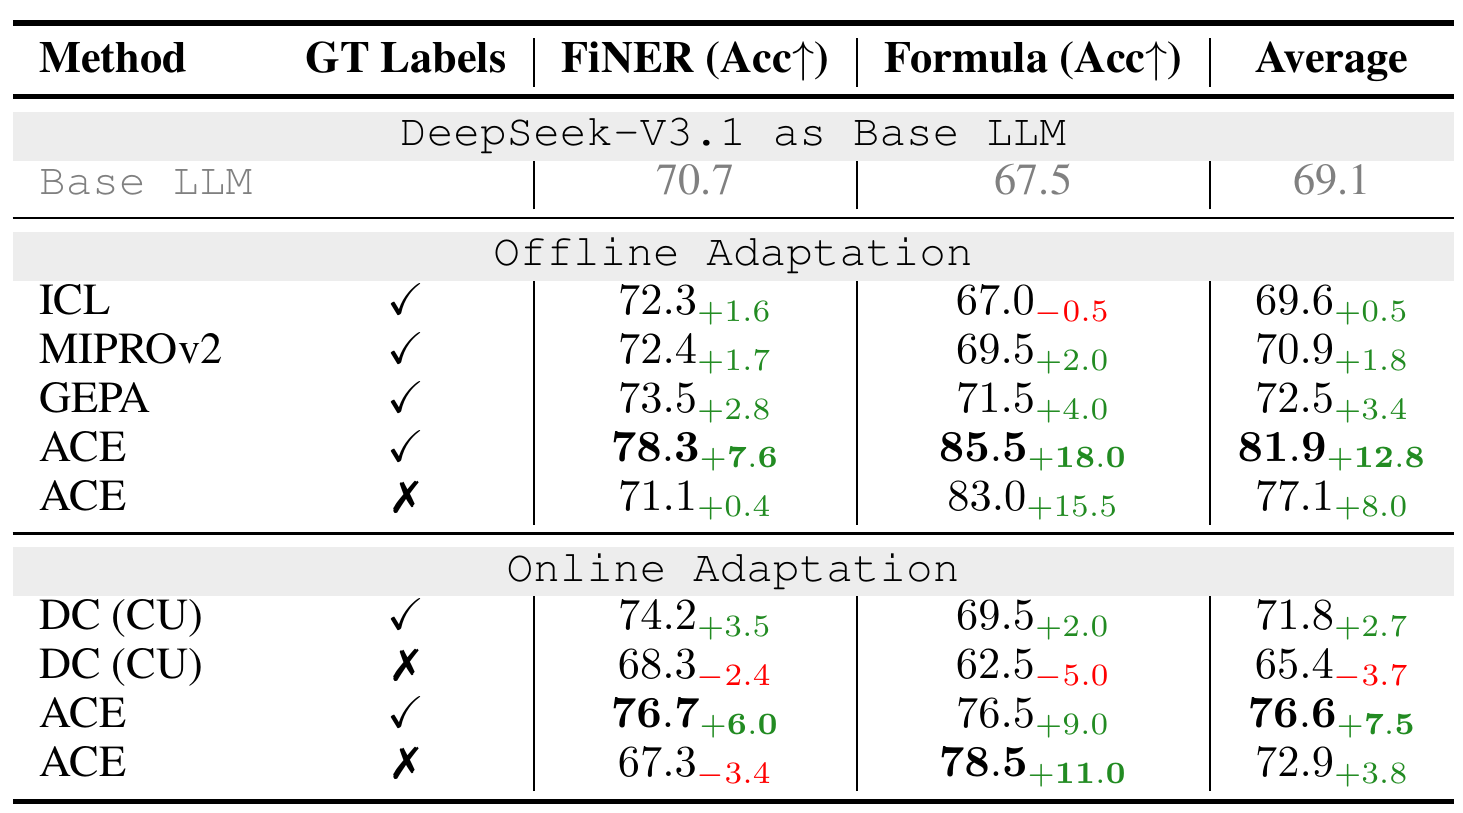
Some runs supply ground-truth labels, while others rely on execution feedback. The overview chart below mixes those settings, so the original tables are needed for fair comparisons.
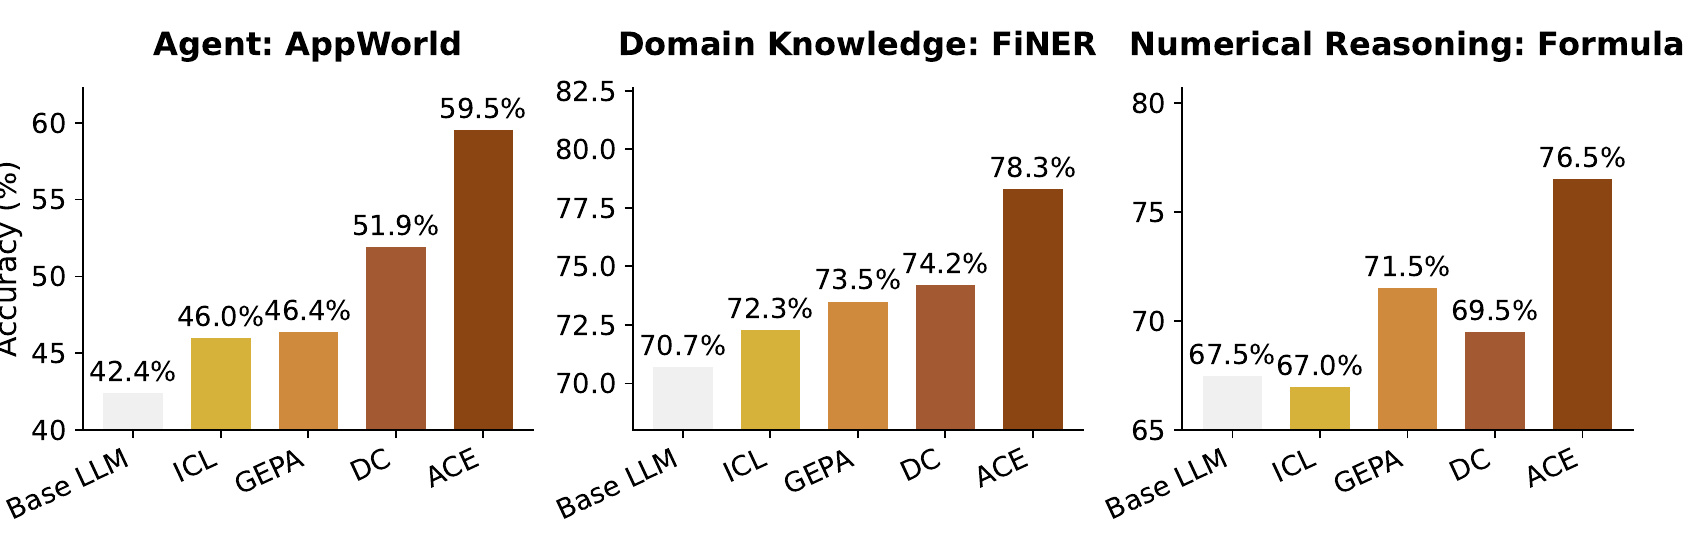
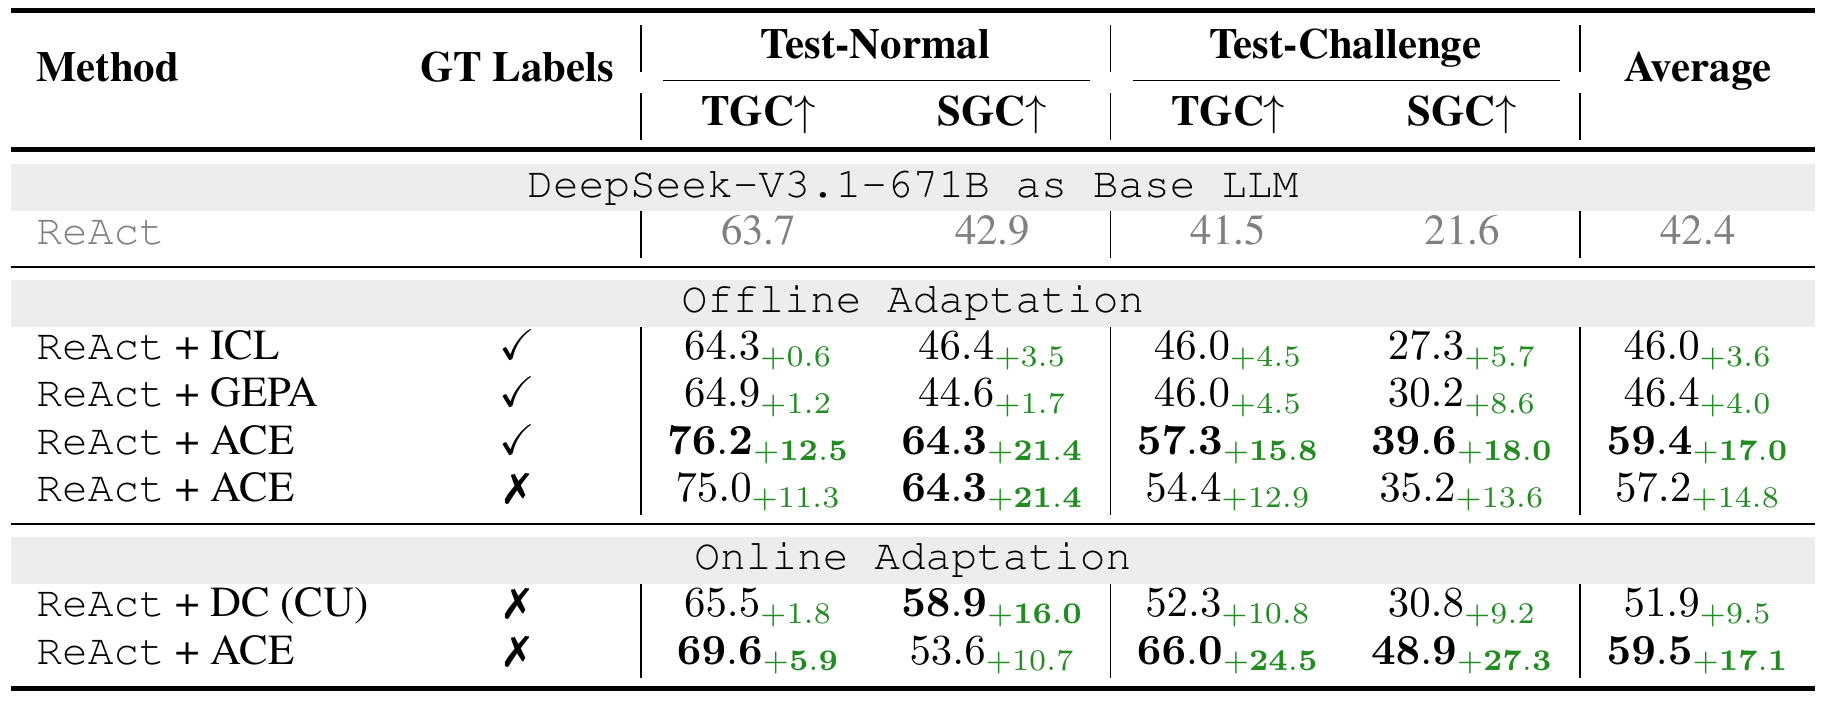
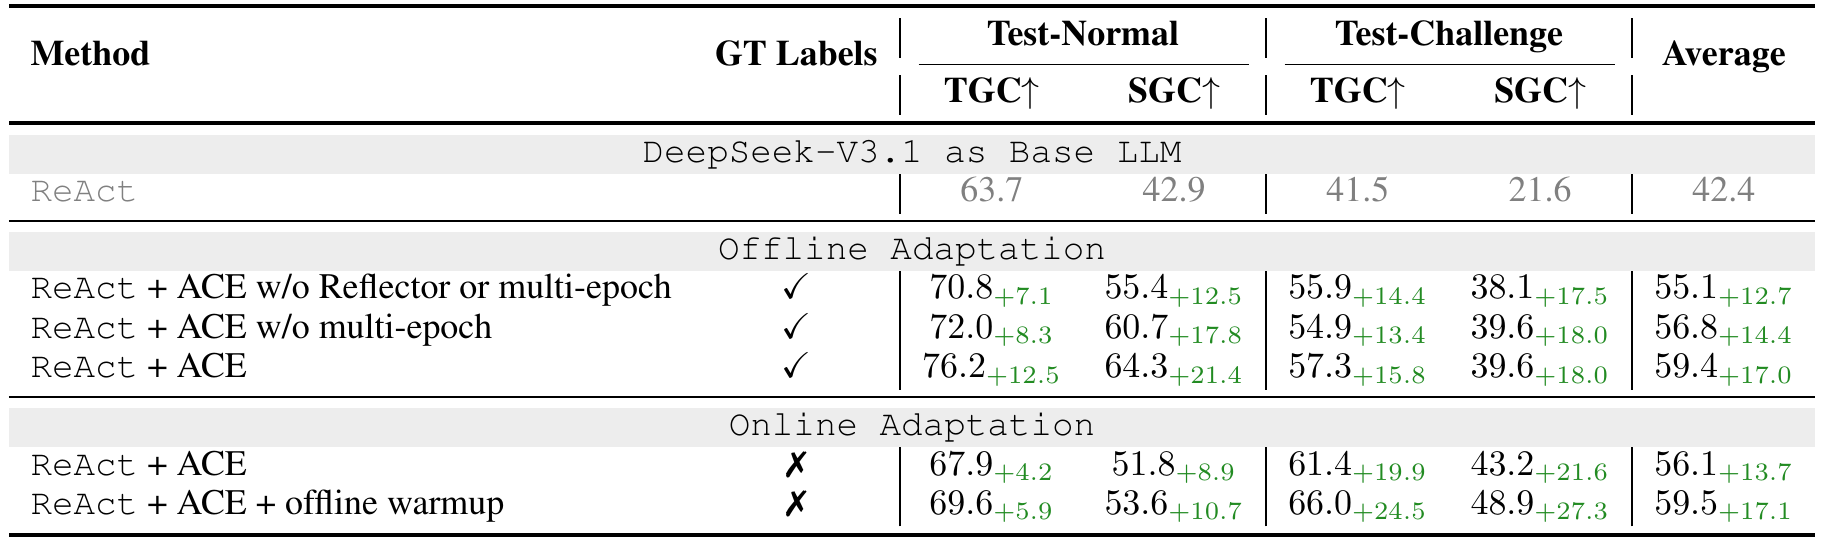
On AppWorld, agents use APIs and code to complete tasks, with performance measured across both regular and challenge scenarios. Using the same DeepSeek-V3.1 backbone, offline ACE achieved a noticeably higher score than GEPA, while online ACE also outperformed Dynamic Cheatsheet after offline warmup.
Overall, the results show that ACE provided a clear performance advantage in both the offline and online settings tested.
The finance results show both the promise and the boundary. With labeled offline adaptation, ACE averaged 81.9% across FiNER and Formula versus 72.5% for GEPA. Yet online ACE without labels fell below the base model on FiNER: 67.3% versus 70.7%. Formula improved in that same no-label setting. A plausible reflection can become a bad rule when the task offers no dependable outcome signal.
Which parts of ACE earned their place
The authors also tested what happened when parts of ACE were removed. On AppWorld, the full system performed better than versions without multi-epoch adaptation or the dedicated Reflector. In the online setting, adding offline warmup also improved performance.
ACE also made the adaptation process much faster on the workloads tested. In the offline AppWorld test, it took far less time than GEPA, while the online FiNER setup was also considerably quicker and cheaper than Dynamic Cheatsheet. These figures measure the learning stage, not the time or cost of handling an individual user request. And while a longer playbook can improve future performance, it can also increase the amount of information the agent has to process at inference time.
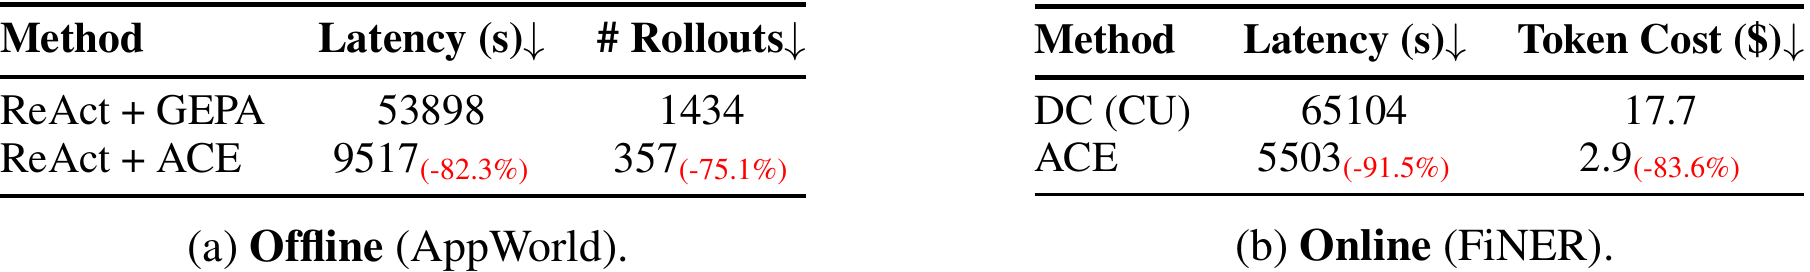
When to use an evolving playbook
ACE is most relevant when tasks repeat, successful outcomes can be checked, and small procedural lessons transfer to later work. The paper itself says some tasks, including HotPotQA and Game of 24, may need only concise rules. Its no-label FiNER result shows the other limit: weak feedback can pollute a playbook.
If you test ACE in an application, compare it with a fixed-context baseline on held-out tasks. Track task success, playbook changes, and how often a rule later proves harmful. Keep the feedback signal explicit. The authors’ code provides an implementation and a concrete playbook format.
The takeaway
ACE’s key idea is simple: let agents turn useful experience into small, traceable updates that improve what future agents read and do.
The results show that this can make agents substantially better at tasks where reusable knowledge and feedback matter. But memory alone is not enough. The update process has to be grounded in evidence, or agents can repeatedly learn and pass along the wrong lesson.
Ultimately, ACE points toward a more practical way for agents to improve over time: learning from past experience instead of starting from scratch on every task.
Note: Some of the images used in this article were from the Agentic Context Engineering paper.
Frequently Asked Questions
Q1. What is Agentic Context Engineering (ACE)?
A. ACE is a framework that helps AI agents improve performance by dynamically updating their context playbooks without modifying model weights.
Q2. How does ACE prevent information loss during updates?
A. Instead of full context rewrites, ACE applies small, incremental delta updates to modular context entries to preserve learned details.
Q3. What core components make up the ACE feedback loop?
A. The loop consists of three main parts: a Generator attempting tasks, a Reflector extracting insights, and a Curator updating the playbook.
Studying, evaluating, and explaining AI systems for over 6 years.
“𝘖𝘯𝘤𝘦 𝘮𝘦𝘯 𝘵𝘶𝘳𝘯𝘦𝘥 𝘵𝘩𝘦𝘪𝘳 𝘵𝘩𝘪𝘯𝘬𝘪𝘯𝘨 𝘰𝘷𝘦𝘳 𝘵𝘰 𝘮𝘢𝘤𝘩𝘪𝘯𝘦𝘴 𝘪𝘯 𝘵𝘩𝘦 𝘩𝘰𝘱𝘦 𝘵𝘩𝘢𝘵 𝘵𝘩𝘪𝘴 𝘸𝘰𝘶𝘭𝘥 𝘴𝘦𝘵 𝘵𝘩𝘦𝘮 𝘧𝘳𝘦𝘦. 𝘉𝘶𝘵 𝘵𝘩𝘢𝘵 𝘰𝘯𝘭𝘺 𝘱𝘦𝘳𝘮𝘪𝘵𝘵𝘦𝘥 𝘰𝘵𝘩𝘦𝘳 𝘮𝘦𝘯 𝘸𝘪𝘵𝘩 𝘮𝘢𝘤𝘩𝘪𝘯𝘦𝘴 𝘵𝘰 𝘦𝘯𝘴𝘭𝘢𝘷𝘦 𝘵𝘩𝘦𝘮.” — 𝖥𝗋𝖺𝗇𝗄 𝖧𝖾𝗋𝖻𝖾𝗋𝗍, 𝖣𝗎𝗇𝖾